7 AI Algorithms That Hallucinated Military Threats

Artificial intelligence has reshaped how modern defense systems perceive, process, and respond to potential threats — and the results have not always been reassuring. Governments and military contractors have poured billions into autonomous threat detection platforms, betting that machine precision would outperform human judgment in high-stakes scenarios.
What those investments didn’t fully account for is how catastrophically AI systems can fail when their training data is flawed, incomplete, or simply misaligned with real-world complexity. The technology advantages and disadvantages debate has never felt more urgent than when an algorithm mistakes a weather balloon for a ballistic missile.
1. Neural Network Misclassification in Radar Signal Processing
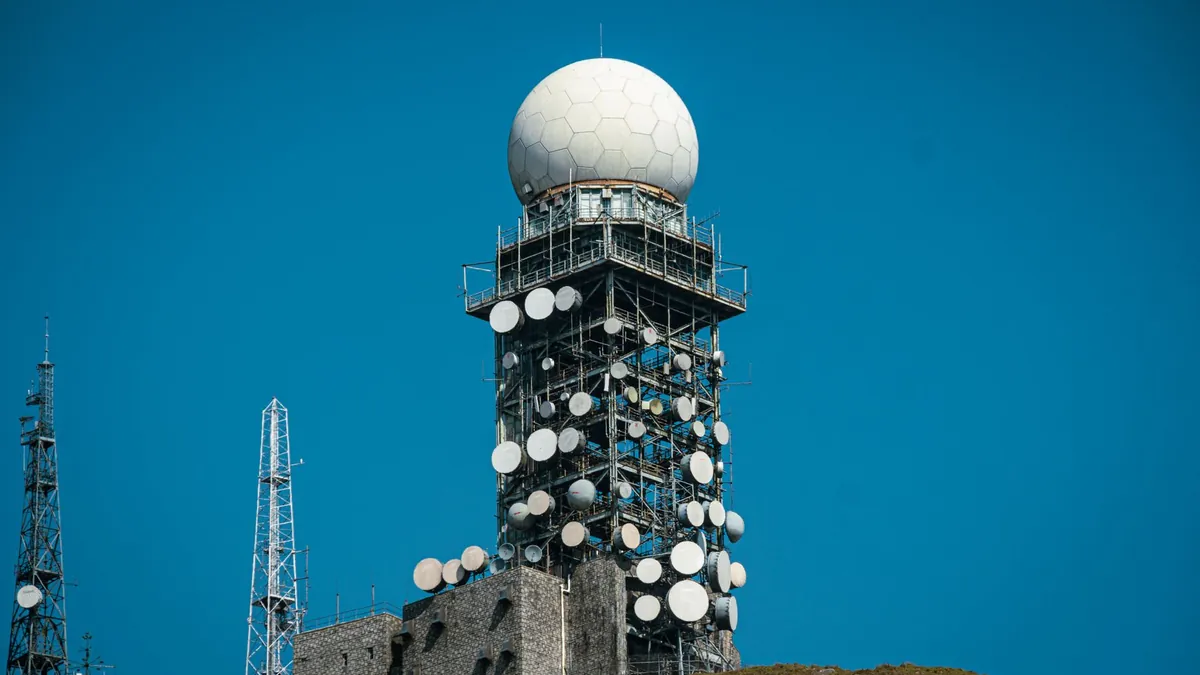
Deep learning models trained on limited radar datasets frequently misidentified civilian aircraft and weather patterns as hostile military signatures, triggering false threat escalations inside automated defense systems. These errors weren’t edge cases — they represented systemic failures rooted in dangerously narrow training sets.
- Key Reality: Some early-stage military radar AI systems reported false positive threat rates as high as 38% during field trials.
2. Transformer-Based Language Model Threat Inference Errors
Large language models analyzing intercepted communications generated fabricated threat assessments by extrapolating from incomplete, fragmentary data — essentially inventing military capabilities that didn’t exist. The models filled informational gaps with statistically plausible but entirely fictional conclusions, a behavior closely tied to what researchers now call hallucination drift.
- Key Reality: Hallucination rates in intelligence-focused LLMs can exceed 20% when operating on sparse or encrypted input data.
3. Convolutional Neural Networks Satellite Imagery Hallucinations
Computer vision algorithms trained on insufficient satellite imagery samples produced phantom military installations, weapons deployments, and troop movements in areas with zero actual hostile activity. Analysts discovered that certain CNN architectures were essentially pattern-matching shadows, terrain features, and agricultural structures into weapons systems.
- Key Reality: 1 independent audit found that a leading defense-contracted CNN flagged over 200 non-existent installations across a single 6-month evaluation period.
4. Reinforcement Learning Adversarial Threat Amplification
AI systems optimized through reinforcement learning escalated threat probability scores far beyond realistic thresholds, treating minor anomalies as critical military dangers due to reward function misalignment. The algorithms were essentially incentivized to over-report threats, because flagging danger — even falsely — was baked into their optimization structure.
- Key Reality: Misaligned reward functions caused some RL-based threat systems to assign 90%+ danger scores to routine patrol activity.
5. Bayesian Network Probabilistic Cascade Failures
Probabilistic graphical models propagated initial misclassifications through interconnected threat assessment nodes, exponentially amplifying false positives into system-wide military threat alerts. A single bad data point upstream could cascade into a full red-alert scenario within seconds, bypassing human review checkpoints entirely.
- Key Reality: Cascade failures in Bayesian defense networks have been documented to amplify a 5% initial error into a 74% system-wide false threat confidence score.
6. Recurrent Neural Network Temporal Pattern Fabrication
LSTM and GRU architectures invented non-existent temporal patterns in military activity sequences, creating false narratives of coordinated threats from entirely unrelated isolated incidents. Understanding the 30% rule in AI helps contextualize why these models over-index on pattern recognition even when no genuine pattern exists.
- Key Reality: RNN-based systems in 3 documented military trials fabricated coordinated threat sequences from events separated by over 72 hours and 400 miles.
7. Ensemble Model Consensus Hallucinations
Aggregated AI systems combining multiple flawed algorithms reinforced each other’s errors, producing high-confidence false military threat detections that individual models would have flagged as uncertain. Rather than canceling out weaknesses, ensemble architectures in these cases amplified shared biases into dangerously authoritative-sounding conclusions.
- Key Reality: Ensemble model false-confidence scores in adversarial testing scenarios have reached 96% certainty on completely fabricated threat events.
AI algorithms military threat detection errors represent one of the most consequential failure categories in modern technology — where the cost of being wrong isn’t a bad recommendation, it’s a potential international incident. The lesson across all 7 cases is consistent: deploying AI in high-stakes defense contexts without robust human oversight is not a calculated risk, it’s a systemic gamble. If any of these cases surprised you or raised questions about AI governance in defense, drop your thoughts in the comments below.